Artificial Intelligence
This space is about returning to the roots of programming while staying curious about where it’s headed. It’s a place to revisit core concepts — variables, loops, data structures, logic — and see them with fresh eyes. Whether you’re brushing up on fundamentals or diving into new paradigms, the goal is clarity, confidence, and creative problem-solving.
I’ll be exploring classic topics alongside modern techniques, sharing experiments, breakdowns, and reflections on how I approach code today. From understanding how arrays really work to visualizing trees and queues, this journey is about building a deeper, more intuitive grasp of how software behaves.
Coding isn’t just technical — it’s expressive. And this space is for anyone who wants to sharpen their skills, rethink old habits, and grow as a developer by reconnecting with the building blocks.

Prompt Engineering
Prompt engineering is the practice of designing clear, structured instructions that help AI models produce better, more accurate results. It’s all about choosing the right wording, adding context, and guiding the model toward the outcome you want. Good prompts turn vague ideas into useful responses, making AI a powerful tool for coding, writing, and problem‑solving.
AI Agents and Automation
For most of AI's history, models could only respond — you asked a question, it gave an answer. AI agents change that. An agent is an AI that can take actions: it can browse the web, write and run code, send emails, search databases, and make decisions — all on its own, step by step, to complete a goal you give it.
Think of it like the difference between asking someone for directions versus hiring a driver. The model goes from answering to actually doing.
To make this work, agents rely on a few key ideas. First, tool use — giving the AI access to external capabilities like a calculator, a search engine, or an API. Second, memory — letting the agent remember what it has already done so it doesn't repeat itself or lose track. Third, planning — breaking a big goal into smaller steps and deciding what to do next at each stage.
Agents can also work in teams. Multi-agent systems have multiple AI models collaborating, each handling a different part of a task, with one acting as an orchestrator directing the others. This mirrors how a real team works.
Popular frameworks like LangChain and AutoGPT made this approachable by giving developers ready-made building blocks to wire these pieces together. Today, major products like customer support bots, coding assistants, and research tools are all built on agentic foundations.
Understanding agents matters because it represents the shift from AI as a tool you talk to, to AI as something that works alongside you.
How AI Learns
When most people think of learning, they picture a classroom — a teacher explains something, a student takes notes, and knowledge is transferred. Machine learning works differently. Instead of being taught rules, an AI learns by looking at examples until it figures out the patterns on its own.
There are three main ways this happens.
The first is supervised learning. You show the AI thousands of labeled examples — pictures of cats labeled "cat," pictures of dogs labeled "dog" — and it gradually learns what features separate one from the other. Once trained, it can look at a photo it has never seen before and make a reasonable guess. Most of the AI you interact with daily, from spam filters to recommendation engines, works this way.
The second is unsupervised learning. Here, the AI gets data with no labels at all. It has to find structure on its own — grouping similar things together, spotting patterns nobody told it to look for. Companies use this to segment customers into groups without knowing in advance what those groups will look like.
The third is reinforcement learning. This one is closest to how humans learn through experience. The AI takes actions, receives feedback in the form of rewards or penalties, and gradually figures out which actions lead to better outcomes. This is how AI learned to play chess and Go at a superhuman level — not by being taught moves, but by playing millions of games against itself and learning from what worked.
What makes all three powerful is that none of them require a human to manually write the rules. The AI finds the rules itself, hidden inside the data.
Large Language Model
A large language model, or LLM, is the technology behind tools like ChatGPT, Claude, and Gemini. Understanding what it actually is — not just what it does — changes how you use it and why you trust it the way you would trust any other tool: carefully and with context.
At its core, an LLM is a system trained to predict what comes next in a sequence of text. That sounds simple, but the scale of it is what makes it powerful. These models are trained on enormous amounts of written text — books, articles, websites, code — and through that process they develop an internal representation of how language, ideas, and facts connect to one another.
When you type a prompt, the model does not look up an answer in a database. It generates a response one piece at a time, each piece chosen based on what is most likely to follow everything that came before it. Those pieces are called tokens — roughly chunks of a word — and a model processes thousands of them at once.
This is also why LLMs sometimes get things wrong. They are not retrieving facts; they are generating text that looks like the kind of text that would answer your question. If the training data contained something wrong, or if the model is pushed into territory it has little data on, it can produce a confident-sounding answer that is simply incorrect. This is called a hallucination, and it is not a bug in the traditional sense — it is a structural feature of how these models work.
RAG-How AI Uses Your Documents
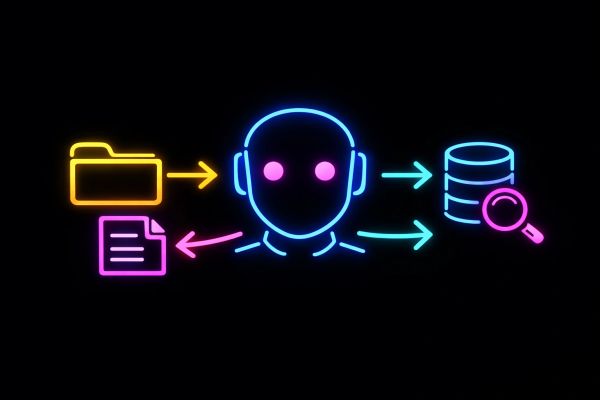
LLMs know a lot, but they have a hard limit: they only know what was in their training data, and that data has a cutoff date. Ask an LLM about something that happened last week, or about a document that lives on your company's internal drive, and it will either make something up or tell you it does not know.
RAG, which stands for Retrieval-Augmented Generation, is the solution to this problem. Instead of relying purely on what the model already knows, RAG gives the model access to a relevant piece of information right before it responds — pulled fresh from a database, a document, or a search engine.
Here is how it works in practice. You have a support chatbot for a software company. A user asks why their account is not syncing. Without RAG, the model guesses based on general knowledge. With RAG, the system first searches the company's own documentation, finds the relevant troubleshooting page, and feeds that content directly into the prompt. The model then answers using the actual documentation, not a guess.
The key pieces that make this work are embeddings and vector databases. An embedding is a way of turning a piece of text into a list of numbers that captures its meaning. A vector database stores thousands of these embeddings and can instantly find the ones most similar to a new question. When a user asks something, their question is turned into an embedding, the database finds the closest matches, and those matches get handed to the model as context.
AI Hallucination
If you have used an AI tool for long enough, you have probably caught it saying something wrong yet confidently. A fake statistic. A book that does not exist. A law that was never passed. This is called a hallucination, and it is one of the most important things to understand about how these systems work.
The word "hallucination" implies the AI is imagining things, which is a useful way to think about it. But the deeper explanation is more structural. An LLM does not store facts the way a database does. It learns patterns from enormous amounts of text, and when it generates a response, it is producing what sounds most plausible given everything it has processed — not retrieving a verified answer from a reliable source.
This means that when the model does not know something, it does not always say so. Instead, it continues generating text that fits the shape of a confident answer. The tone stays the same whether the model is certain or completely guessing, which is what makes hallucinations so easy to miss.
Several things make hallucinations more likely. Asking about very specific or niche topics gives the model less reliable training data to draw on. Asking about recent events pushes it past its knowledge cutoff. And asking leading questions can nudge the model toward confirming something false rather than questioning it.
The ways to reduce hallucinations are also worth knowing. RAG grounds responses in real documents rather than the model's internal knowledge. Asking the model to cite its sources forces it to be specific, making errors easier to spot. And treating AI output the way you would treat a first draft. Useful, but worth checking is the best practice.
Cybersecurity fundamentals
Before you can understand any specific security threat, attack, or defence, there is a framework that sits underneath all of it. It is called the CIA triad, and it is the lens through which every security professional looks at a system.
CIA stands for confidentiality, integrity, and availability. These are the three properties that any secure system needs to protect, and almost every security decision is ultimately about preserving one or more of them.
Confidentiality means that information is only accessible to the people who are supposed to see it. When you log into your bank account, confidentiality is what ensures that only you can see your balance — not the person sitting next to you in a café, and not an attacker who intercepted your connection. Encryption, passwords, and access controls all exist to enforce confidentiality.
Integrity means that information has not been tampered with. It is not just about keeping data secret — it is about knowing that data is accurate and has not been modified by someone who should not have touched it. When you download software, the checksum you sometimes see is an integrity check. It lets you verify that what you downloaded is exactly what the developer released, with nothing added or changed in transit.
Availability means that systems and data are accessible when the people who need them actually need them. A hospital whose patient records are locked by ransomware has an availability problem. A website that goes offline under a flood of fake traffic — a DDoS attack — has an availability problem. Security is not just about keeping bad actors out; it is also about keeping systems running for the people who depend on them.
Most real-world attacks can be mapped to one of these three. Understanding the CIA triad does not make you an expert, but it gives you a way to ask the right questions about any system you are looking at.
What is a neural network?
The term neural network gets used constantly in conversations about AI, often without much explanation. It sounds technical and biological at the same time, which can make it feel harder to understand than it actually is. The core idea is surprisingly approachable.
A neural network is a system loosely inspired by the way the human brain processes information — not a direct copy of it, but a structure that borrows the same basic logic. The brain is made up of billions of neurons connected to one another. When a signal comes in, it travels through those connections, gets processed, and produces some kind of output. A neural network does something similar, but with numbers and mathematics instead of biology.
The structure has three parts. There is an input layer, which receives the raw data — pixels in an image, words in a sentence, numbers in a spreadsheet. There is an output layer, which produces the result — a classification, a prediction, a generated piece of text. And between them are hidden layers, where the actual processing happens. Each layer transforms the data it receives and passes it forward.
What makes a network learn is the weights on the connections between neurons. At the start, these weights are essentially random. The network makes a guess, compares it to the correct answer, measures how wrong it was, and then adjusts the weights slightly to do better next time. This process — called backpropagation — repeats millions of times across millions of examples until the network becomes accurate.
A deep neural network is simply one with many hidden layers. The word "deep" in deep learning refers to this depth. Each layer tends to learn something different — in image recognition, early layers might detect edges, middle layers might recognise shapes, and later layers might identify objects. The complexity emerges from the layers working together, not from any single part being clever on its own.
The difference between AI, machine learning, and deep learni
These three terms are used interchangeably in most conversations, which makes them feel like synonyms. They are not. They are nested inside one another, and understanding the relationship between them gives you a much clearer picture of what people are actually talking about when they use each one.
Start with AI — artificial intelligence. This is the broadest term. It refers to any system that performs tasks that would normally require human intelligence. That definition is deliberately wide. A chess engine from the 1990s that follows hand-coded rules counts as AI. A spam filter counts as AI. A system that generates photorealistic images from a text description counts as AI. The common thread is that the machine is doing something that looks intelligent, regardless of how it achieves that.
Machine learning is a subset of AI. It refers specifically to systems that learn from data rather than following rules that a human explicitly programmed. Instead of writing a rule that says "if the email contains the word 'urgent' and has a suspicious sender, mark it as spam," a machine learning system is shown thousands of spam emails and thousands of legitimate ones, and it figures out the distinguishing patterns on its own. The key difference from traditional AI is that the system improves through experience rather than through manual updates to its code.
Deep learning is a subset of machine learning. It refers specifically to machine learning that uses neural networks with many layers — the architecture described in the previous post. What separates deep learning from earlier machine learning approaches is its ability to handle raw, unstructured data like images, audio, and text without needing a human to manually identify which features matter. The network learns the relevant features itself, from the data, through its layers.
So the relationship is this: all deep learning is machine learning, and all machine learning is AI, but not all AI is machine learning, and not all machine learning is deep learning. When someone says "AI" in 2025, they usually mean deep learning specifically — but knowing the distinctions tells you what they are really describing.